TTS for AI character chat and companions
Bring your character chat and AI companions to life with AI voices that express each character’s charm. Connect quickly and easily through the API and MCP.
 heavystep
AI voices that bring out your companion’s charm
Go beyond a voice that sounds human for an AI. Choose an AI voice you could truly fall for—one that could become your favorite. Let voice bring your companion to life.
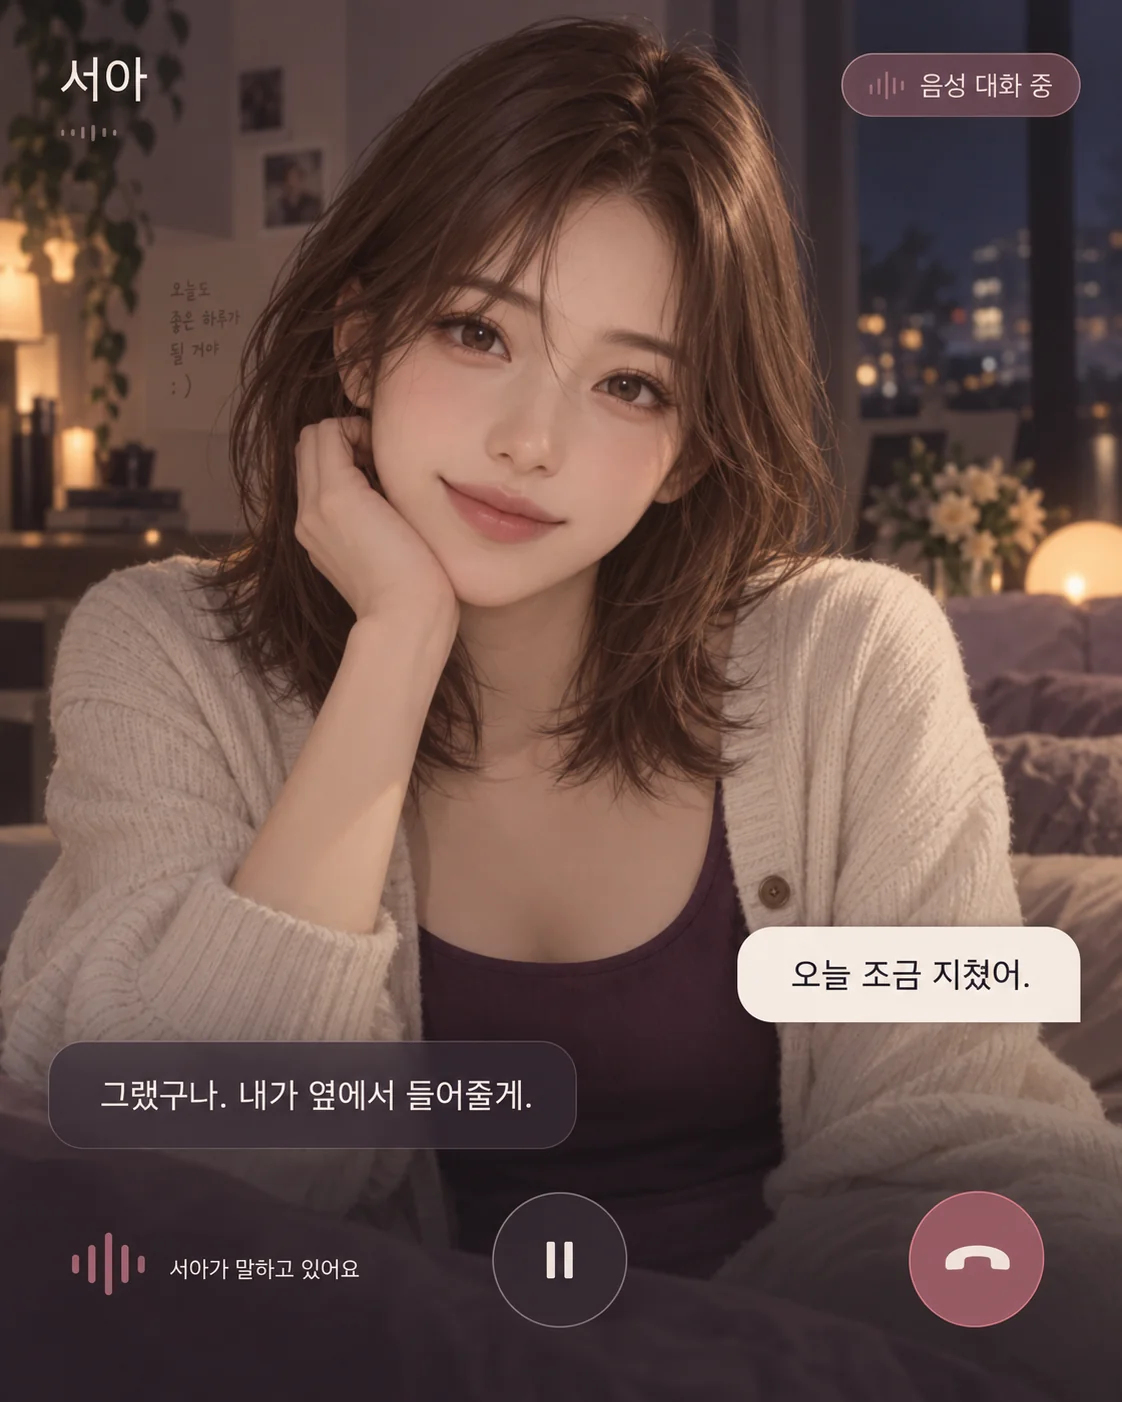
A conversation with a character who feels right here
Build conversations with characters using streaming STT and TTS APIs. With a time to first audio of less than one second, the experience can feel like talking face to face.
New voice IP every month, no extra IP fees
You don’t need a new contract for every new character. Choose the best-fitting voice from the voice IP available through Kitsch Labs.
Listen to character voices
Give your companion a voice
Choose a voice that fits your character and start a conversation that feels closer.
Get startedFrequently asked questions
Does TTS generate the conversation too?
TTS turns supplied text into speech. Implement dialogue generation and memory in your service, then send the resulting text to the speech API.
Should I use the service API or agent tools?
Use the HTTP API to build your service’s audio input and output flow. MCP connects agents to audio tools. Implement real-time input and playback to suit your client.
How do I choose a voice for my character?
Define the character’s personality, age, and relationship with the user, then compare the same lines across voices. Try comforting lines, playful exchanges, and longer explanations as well as greetings.
How do I build a voice conversation with a companion?
Convert user speech to text with STT, generate a reply with your dialogue model, and turn that reply into speech with TTS. Connect streaming input and output, and plan how playback stops when the user starts speaking again.
What does TTFA mean?
Time to first audio is the time from a speech generation request to the arrival of the first audio. The time before a user hears a reply also includes speech recognition, dialogue model response, networking, and playback preparation.
Can I listen to voices before integrating the API?
Listen to samples in the voice cards on this page. Check character details and supported languages on each profile, and try your service’s dialogue with web speech generation first.
How do I keep the same voice throughout a conversation?
Assign a voice ID to each character and reuse it for subsequent lines. Keep speaking style and sentence length aligned with the character, then check pronunciation and tone in a real dialogue flow.
Does no extra IP fee mean speech generation is free?
No extra IP fee refers to the separate contracting cost of adopting catalog voice IP. Speech generation usage is separate and consumes credits according to your plan and credit policy. Each voice’s usage terms also apply.